Introduction
Welcome to S1! This is where we start turning messy lists of numbers into meaningful information. Think of yourself as a data detective. In this chapter, we're going to build your essential toolkit. First, we'll master Statistical Diagrams like histograms and box-and-whisker plots to visually represent data and spot patterns. Then, we'll dive into Measures of Central Tendency (your classic mean, median, and mode) to find the 'average' or 'typical' value in a dataset. But that's only half the story! We'll also explore Measures of Variation like standard deviation to understand how spread out or consistent the data is. Finally, we'll learn a clever exam trick called Coded Data to make tough calculations way easier. By the end of this, you'll be able to look at any dataset and tell its story. Let's get started! 💪
Analysis and Interpretation of Statistical Diagrams5.1
Alright, let's get visual! Raw data is like a phone book – all the info is there, but it's a nightmare to interpret. Statistical diagrams are your secret weapon to turn that chaos into clarity, and they are essential for acing S1. First up, the stem-and-leaf diagram. It's brilliant because it groups the data while keeping the original values. Super useful for seeing the shape of the distribution. For comparing two datasets, like the exam scores of two different classes, we use a back-to-back stem-and-leaf diagram. Next, we have the box-and-whisker plot, the MVP of visual comparison. It gives you a five-number summary (Min, Q1, Median, Q3, Max) in one clean graphic. You can instantly compare the median, the interquartile range (IQR, which is $Q_3 - Q_1$), and check for skewness. This is a skill you'll use constantly in university research projects. 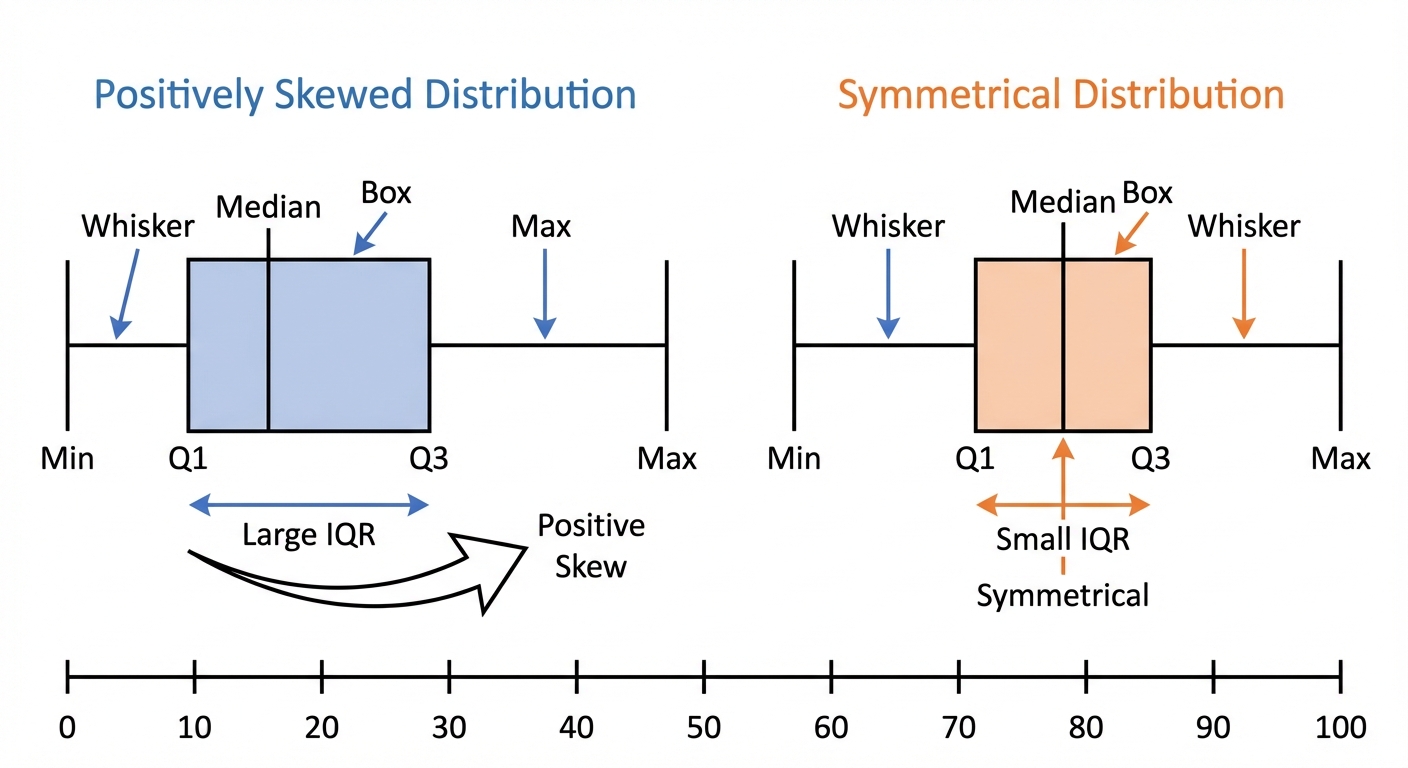 <br><br>Now for the big one: histograms. Warning: these are NOT bar charts. Histograms are for continuous data, and the absolute key is that the area of each bar represents the frequency. This means when you have unequal class widths (which examiners love to use), you MUST plot frequency density on the y-axis. Remember this formula: $$Frequency \ Density = \frac{Frequency}{Class \ Width}$$ Finally, we have the cumulative frequency graph (or ogive). This shows a running total. It’s perfect for estimating percentiles, like the median ($50^{th}$ percentile) or the upper and lower quartiles ($75^{th}$ and $25^{th}$ percentiles). This is foundational for careers in everything from finance (analysing stock returns) to medicine (studying patient recovery times). Mastering these diagrams isn't just about passing an exam; it's about learning to tell a story with data. 🚀
Worked Example: Constructing a Histogram with Unequal Class Widths5.1
Problem The time, $t$ (in minutes), taken by 50 students to solve a statistics problem is summarised in the table below. Draw a histogram to represent this data.<br><br>| Time ($t$ mins) | Frequency ($f$) |<br>|---|---|<br>| $0 < t \le 10$ | 8 |<br>| $10 < t \le 15$ | 15 |<br>| $15 < t \le 25$ | 20 |<br>| $25 < t \le 30$ | 7 |
Step 1 First, we check the class widths. Notice they are unequal ($10, 5, 10, 5$). This is a huge red flag that we can't just plot frequency on the y-axis. We must calculate the frequency density for each class. The formula is your best friend here. $$Frequency \ Density \ (FD) = \frac{Frequency \ (f)}{Class \ Width \ (CW)}$$
Step 2 Let's calculate the class width and then the frequency density for each group. For the first group, $0 < t \le 10$, the class width is $10 - 0 = 10$. $$FD_1 = \frac{8}{10} = 0.8$$
Step 3 Now, we repeat this for all the other classes and create a new table with our calculated values. This table is what we'll actually use to draw the histogram. | Time ($t$ mins) | $f$ | $CW$ | $FD = f/CW$ |<br>|---|---|---|---|<br>| $0 < t \le 10$ | 8 | 10 | 0.8 |<br>| $10 < t \le 15$ | 15 | 5 | 3.0 |<br>| $15 < t \le 25$ | 20 | 10 | 2.0 |<br>| $25 < t \le 30$ | 7 | 5 | 1.4 |
Step 4 Time to draw! The horizontal axis (x-axis) will be our continuous variable, 'Time ($t$ mins)'. The vertical axis (y-axis) will be 'Frequency Density'. Make sure you choose a suitable scale for both axes. X-axis: Time (from 0 to 30)<br>Y-axis: Frequency Density (from 0 up to at least 3.0)
Step 5 Finally, draw the bars. For each class, the width of the bar is the class width, and the height is the frequency density. For example, the second bar will go from $t=10$ to $t=15$ on the x-axis and have a height of $3.0$. There should be no gaps between the bars. You've now created a perfect histogram! 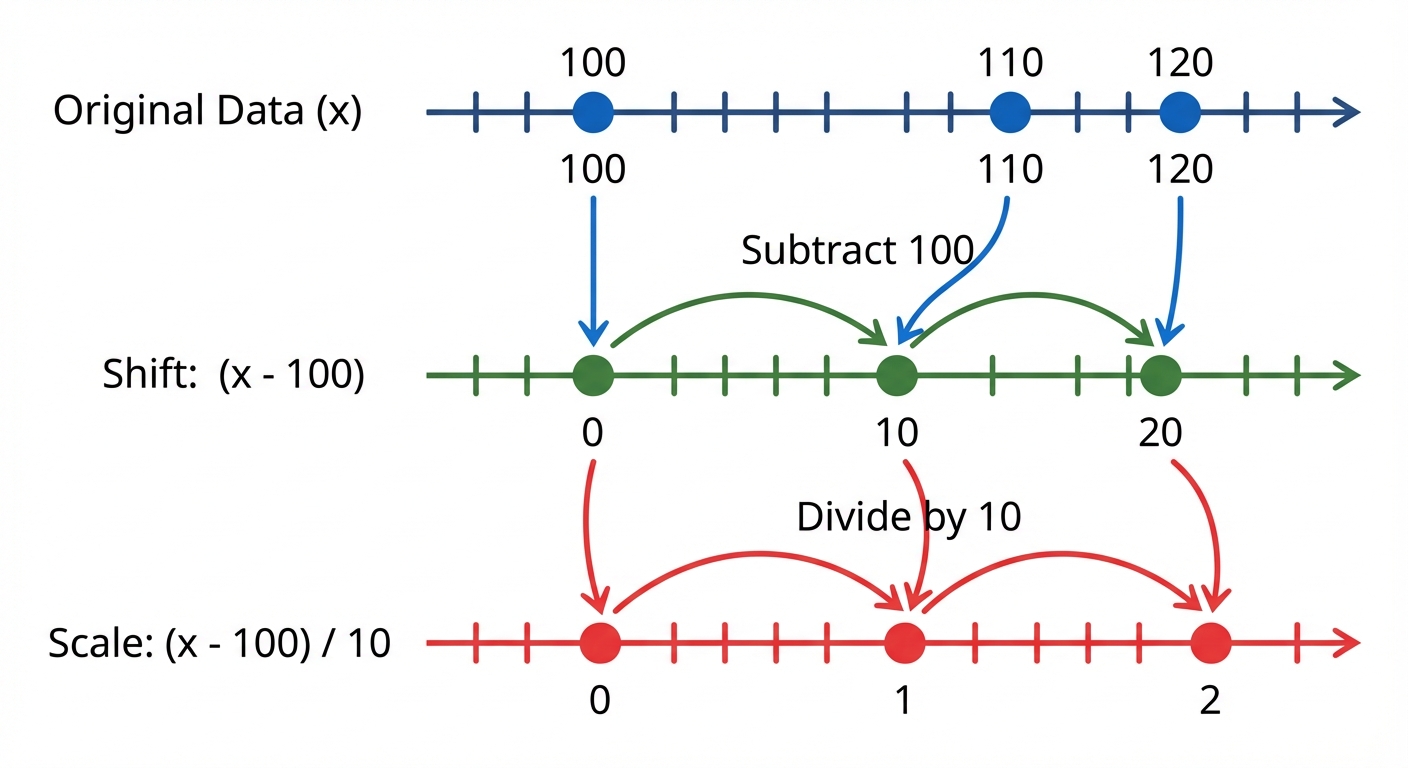 Bar 1: width 10 (0-10), height 0.8<br>Bar 2: width 5 (10-15), height 3.0<br>Bar 3: width 10 (15-25), height 2.0<br>Bar 4: width 5 (25-30), height 1.4
Calculating Mean and Standard Deviation from Coded Data5.1
Okay, let's talk about 'coded data'. Honestly, it sounds way more complicated than it is. Think of it as a 'cheat code' for dealing with massive or annoying numbers. Imagine you're tracking the number of streams for your favourite artist's new album, and the numbers are huge (like 1,250,450, 1,250,510, etc.). Or maybe you're measuring reaction times in a video game in milliseconds, and you get decimals like 0.182s, 0.195s. Doing calculations with these is a pain, right? Coded data is our way of simplifying them first. <br><br> We use a linear code, which usually looks something like this: $y = \frac{x - a}{b}$. Here, '$x$' is your original, clunky data point, and '$y$' is the new, clean, coded version. The 'a' and 'b' are just numbers we choose to make life easier. Subtracting 'a' shifts the data (like moving your entire playlist up or down), and dividing by 'b' scales it (like changing the playback speed). <br><br> So how does this help us find the mean ($\bar{x}$) and standard deviation ($s_x$)? Simple! We calculate the mean and SD for the easy coded data ($\bar{y}$ and $s_y$) first, then we reverse the code to find the original values. <br>For the mean, whatever you did to the data, you do the same to the mean. So, $\bar{y} = \frac{\bar{x} - a}{b}$. To get back to our original mean, we just rearrange: $\bar{x} = b\bar{y} + a$. Easy. <br>For standard deviation, it's a bit different. Remember, SD is all about spread. If you shift all your data by subtracting 'a' (like everyone in your Snapchat group moves 5km north), the distance between you all stays the same. So, subtracting 'a' does not affect the standard deviation. However, scaling by dividing by 'b' squishes or stretches the spread. So, the relationship is just $s_y = \frac{s_x}{b}$, which means our original standard deviation is $s_x = b \times s_y$. Just remember: mean is affected by shift and scale, but SD is only affected by scale. It's a lifesaver in exams!
Worked Example: Calculating Original Mean and SD from Coded Summaries5.1
Problem The time, $x$ seconds, taken by 20 students to complete a puzzle was recorded. The data was simplified using the coding $y = \frac{x - 120}{5}$. The coded data is summarised as $\sum y = 46$ and $\sum y^2 = 138$. Calculate the mean and standard deviation of the time taken, $x$.
Step 1 First up, let's find the mean of our simplified 'y' values. We've got the total ($\sum y$) and the number of students ($n=20$), so this is a piece of cake. $$\bar{y} = \frac{\sum y}{n} = \frac{46}{20} = 2.3$$
Step 2 Now we reverse the cheat code to find the actual mean time, $\bar{x}$. The code was $y = \frac{x - 120}{5}$. So, our shift value is $a=120$ and our scale value is $b=5$. We use the formula $\bar{x} = b\bar{y} + a$. $$\bar{x} = (5 \times 2.3) + 120 = 11.5 + 120 = 131.5 \text{ seconds}$$
Step 3 Time to find the spread of the coded data. We'll use the summary stats formula for standard deviation. Don't forget to use the coded mean, $\bar{y}$, that we just found. $$s_y = \sqrt{\frac{\sum y^2}{n} - \bar{y}^2} = \sqrt{\frac{138}{20} - (2.3)^2} = \sqrt{6.9 - 5.29} = \sqrt{1.61} \approx 1.2688...$$
Step 4 Last step! We need to find the real standard deviation, $s_x$. Remember, the shift ($a=120$) doesn't affect the spread, only the scale ($b=5$) does. So we just multiply our coded SD by $b$. $$s_x = b \times s_y = 5 \times 1.2688... = 6.344 \text{ (3 s.f.)}$$
Measures of Central Tendency5.1
Alright, let's break down 'Measures of Central Tendency'. It sounds super formal, but it's just about finding the 'typical' or 'central' value in a set of data. Think of it like trying to describe your friend group with one person – who's the most representative? We have three main ways to do this:<br><br>1. The Mean (aka the Average): This is the one you probably know. You add up all the values and divide by how many values there are. The formula is $\bar{x} = \frac{\sum x}{n}$. It's like finding the average amount you spend on your food delivery app each month. The mean is great, but it can be heavily skewed by outliers – those extreme values. For example, if your friend who's a pro-gamer joins your casual lobby, their crazy high score will pull the team's mean score way up.<br><br>2. The Median: This is the literal middle value when you line up all your data in order. To find its position, you use $\frac{n+1}{2}$. If you have an even number of data points, you take the mean of the two middle values. The median is your MVP for data with outliers because it doesn't get affected by them. It's the true midpoint, ignoring that one friend who has 10,000 unread Snapchats when everyone else has like, 10.<br><br>3. The Mode: This one's the easiest – it's simply the value that shows up most often. If you listen to one song on repeat all day, that's the mode of your playlist. A dataset can have one mode (unimodal), two modes (bimodal), or more. It's also the only measure you can use for non-numerical data (like the most popular brand of trainers at your school).<br><br>*What about Grouped Data?*<br>Sometimes, you don't get the raw data. Instead, you get a frequency table, like '15 students spent 0-2 hours on homework, 20 students spent 2-4 hours...'. How do you find the mean then? You can't find the exact mean, but you can calculate an Estimated Mean. To do this, you first find the midpoint of each class interval (e.g., the midpoint of 0-2 is 1). You then multiply each midpoint ($x$) by its frequency ($f$) and use the formula: $\bar{x} = \frac{\sum fx}{\sum f}$. For the mode with grouped data, you just find the modal class – the group with the highest frequency. Easy! 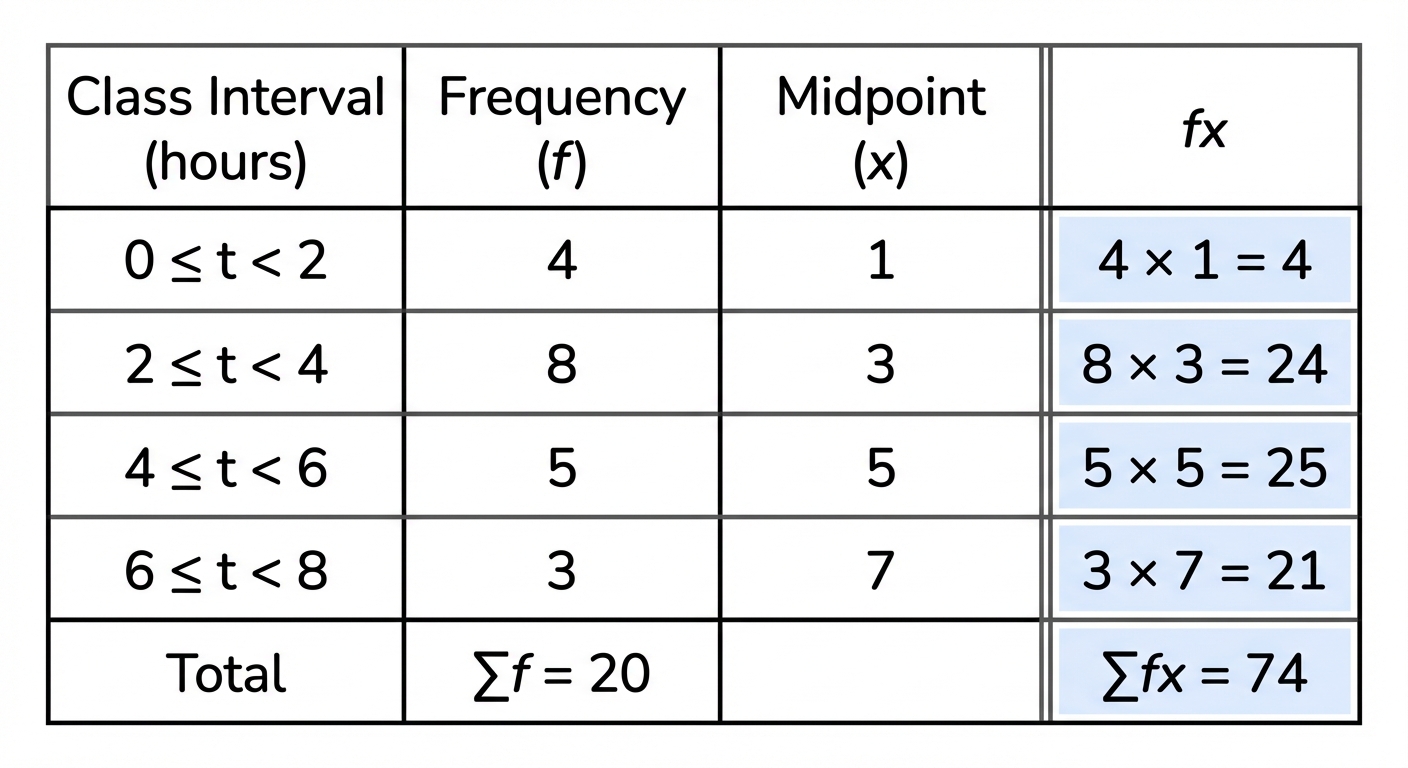
Worked Example: Calculating the Estimated Mean from Grouped Data5.1
Problem The table below shows the number of hours worked in a week by 50 students at their part-time jobs. Estimate the mean number of hours worked.
Step 1 First up, we can't use the time intervals directly. We need a single value to represent each group, so we find the midpoint ($x$) of each class interval. To find the midpoint, just add the upper and lower bounds and divide by 2. Midpoint of $0 \le h < 5$ is $(0+5)/2 = 2.5$<br>Midpoint of $5 \le h < 10$ is $(5+10)/2 = 7.5$<br>Midpoint of $10 \le h < 15$ is $(10+15)/2 = 12.5$<br>Midpoint of $15 \le h < 20$ is $(15+20)/2 = 17.5$
Step 2 Now we need to calculate the total hours worked for each group. We do this by multiplying the midpoint ($x$) by the frequency ($f$) for each row. This gives us our $fx$ column. Think of it as assuming everyone in a group worked the midpoint number of hours. $fx_1 = 12 \times 2.5 = 30$<br>$fx_2 = 20 \times 7.5 = 150$<br>$fx_3 = 13 \times 12.5 = 162.5$<br>$fx_4 = 5 \times 17.5 = 87.5$
Step 3 Next, we need the two big totals for our formula: the total number of students ($\sum f$) and the total estimated hours worked ($\sum fx$). Just sum up the 'frequency' and 'fx' columns. $$\sum f = 12 + 20 + 13 + 5 = 50$$ $$\sum fx = 30 + 150 + 162.5 + 87.5 = 430$$
Step 4 We're at the final boss! Now we just plug our totals into the formula for the estimated mean: $\bar{x} = \frac{\sum fx}{\sum f}$. $$\bar{x} = \frac{430}{50} = 8.6$$
Step 5 Don't forget the context! The question is about hours, so our final answer should be too. So, the estimated mean number of hours worked is 8.6. Also, for extra credit, which is the modal class? It's the one with the highest frequency (20 students), which is $5 \le h < 10$. You got this! 🙌 Estimated Mean = 8.6 hours.
Measures of Variation5.1
So, we've talked about measures of central tendency like the mean and median – they give you the 'average' or 'typical' value. But that's only half the story! Imagine two friends who both average 5 hours of gaming a week. One plays for exactly 5 hours on Saturday, the other plays for 1 hour a day for 5 days and 0 on two. Same average, totally different consistency, right? That's where measures of variation (or spread) come in. They tell us how consistent or spread out the data points are.<br><br>The simplest one is the range, which is just the highest value minus the lowest. It's quick, but it can be easily skewed by one crazy outlier, like that one friend who pulls an all-nighter before a new game release. A much more robust measure is the Interquartile Range (IQR). Think of it as the range of the middle 50% of your crew. We chop off the top 25% and the bottom 25% of the data and find the range of what's left. This gives a better picture of the typical spread. You find it with the formula $IQR = Q_3 - Q_1$, where $Q_3$ is the upper quartile (75th percentile) and $Q_1$ is the lower quartile (25th percentile). 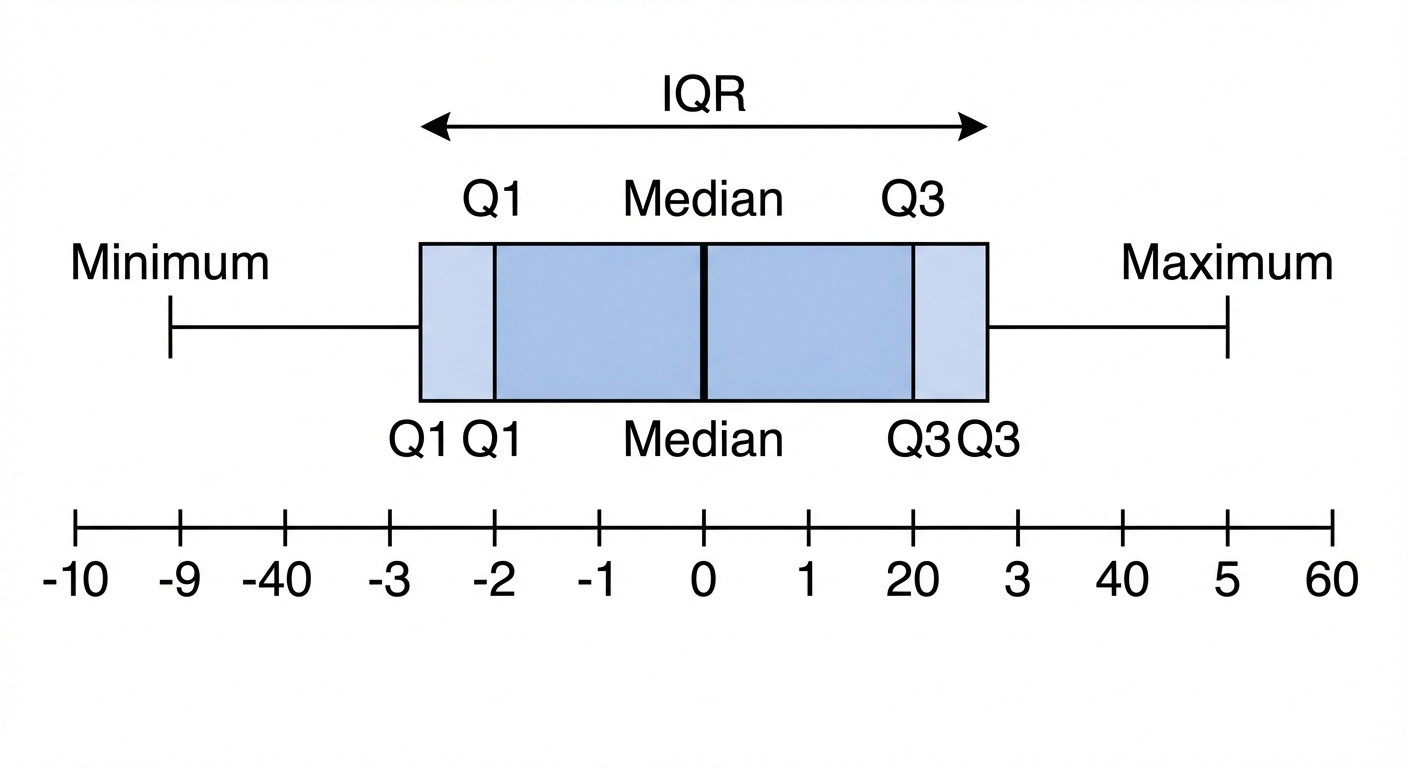 <br><br>But the real MVP of variation is the standard deviation (represented by the Greek letter sigma, $\sigma$). It measures the average distance of every data point from the mean. A small $\sigma$ means your data points are all huddled together, super consistent, like a perfectly curated Spotify playlist. A large $\sigma$ means your data is all over the place. To calculate it, we use the formula $\sigma = \sqrt{\frac{\sum(x - \bar{x})^2}{n}}$ or the easier-to-use version $\sigma = \sqrt{\frac{\sum x^2}{n} - \bar{x}^2}$. The value you get before you square root is called the variance ($\sigma^2$). Don't worry, your calculator does most of the heavy lifting here! Understanding these measures helps you see the full picture, not just the highlight reel average.
Worked Example: Calculating Variation in Part-Time Job Hours5.1
Problem The number of hours a student worked at their part-time job over 8 consecutive weeks are recorded as: 5, 8, 8, 10, 12, 15, 16, 18. Calculate the range, IQR, and the standard deviation for this data.
Step 1 First up, the easiest one: the range. We just find the difference between the maximum and minimum number of hours worked. $$ \text{Range} = \text{Max Value} - \text{Min Value} = 18 - 5 = 13 \text{ hours} $$
Step 2 Now for the IQR. We need to find the lower quartile ($Q_1$) and upper quartile ($Q_3$). Since we have 8 data points, the median ($Q_2$) is between the 4th and 5th values. $Q_1$ is the median of the lower half (5, 8, 8, 10) and $Q_3$ is the median of the upper half (12, 15, 16, 18). $$ Q_1 = \frac{8+8}{2} = 8 \\ Q_3 = \frac{15+16}{2} = 15.5 \\ \text{IQR} = Q_3 - Q_1 = 15.5 - 8 = 7.5 \text{ hours} $$
Step 3 To get the standard deviation, we first need two key ingredients: the mean ($\bar{x}$) and the sum of the squares ($\sum x^2$). Let's calculate those now. $$ \bar{x} = \frac{\sum x}{n} = \frac{5+8+8+10+12+15+16+18}{8} = \frac{92}{8} = 11.5 \\ \sum x^2 = 5^2 + 8^2 + 8^2 + 10^2 + 12^2 + 15^2 + 16^2 + 18^2 = 1198 $$
Step 4 Finally, we plug our values for $n$, $\sum x^2$, and $\bar{x}$ into the standard deviation formula. This will tell us the average spread of weekly hours from the mean. $$ \sigma = \sqrt{\frac{\sum x^2}{n} - \bar{x}^2} = \sqrt{\frac{1198}{8} - (11.5)^2} = \sqrt{149.75 - 132.25} = \sqrt{17.5} \approx 4.18 \text{ hours (3 s.f.)} $$
Key Points to Remember
- Choose the right Statistical Diagram for the job. A histogram shows frequency distribution for continuous data, a box-and-whisker plot is brilliant for comparing medians and interquartile ranges ($IQR$), and a stem-and-leaf diagram keeps the original data visible.
- For Measures of Central Tendency, know when to use each. The mean ($\bar{x} = \frac{\sum x}{n}$) is the most common average but is sensitive to outliers. The median is the middle value and is more robust.
- Measures of Variation tell you about the data's spread. Standard deviation ($\sigma = \sqrt{\frac{\sum x^2}{n} - \bar{x}^2}$) is the key metric; a small $\sigma$ means data is consistent and clustered around the mean.
- Coded Data simplifies big numbers. If you transform data using $y = \frac{x-a}{b}$, remember the mean is affected by both operations ($\bar{x} = b\bar{y} + a$), but the standard deviation is only affected by division ($\sigma_x = |b|\sigma_y$).